Changelogs
Yontrack helps you generate changelogs for many situations:
- from build to build
- across branches
- from a last promotion etc.
These changes logs can be simple, done at branch level level only between two builds, or recursive down the dependencies of a given project.
Changelogs contain a list of issues and/or commits, they can also be based on conventional commits.
Changelogs can be rendered as plain text, Markdown, HTML and other formats are available.
How to generate a changelog
Using the UI
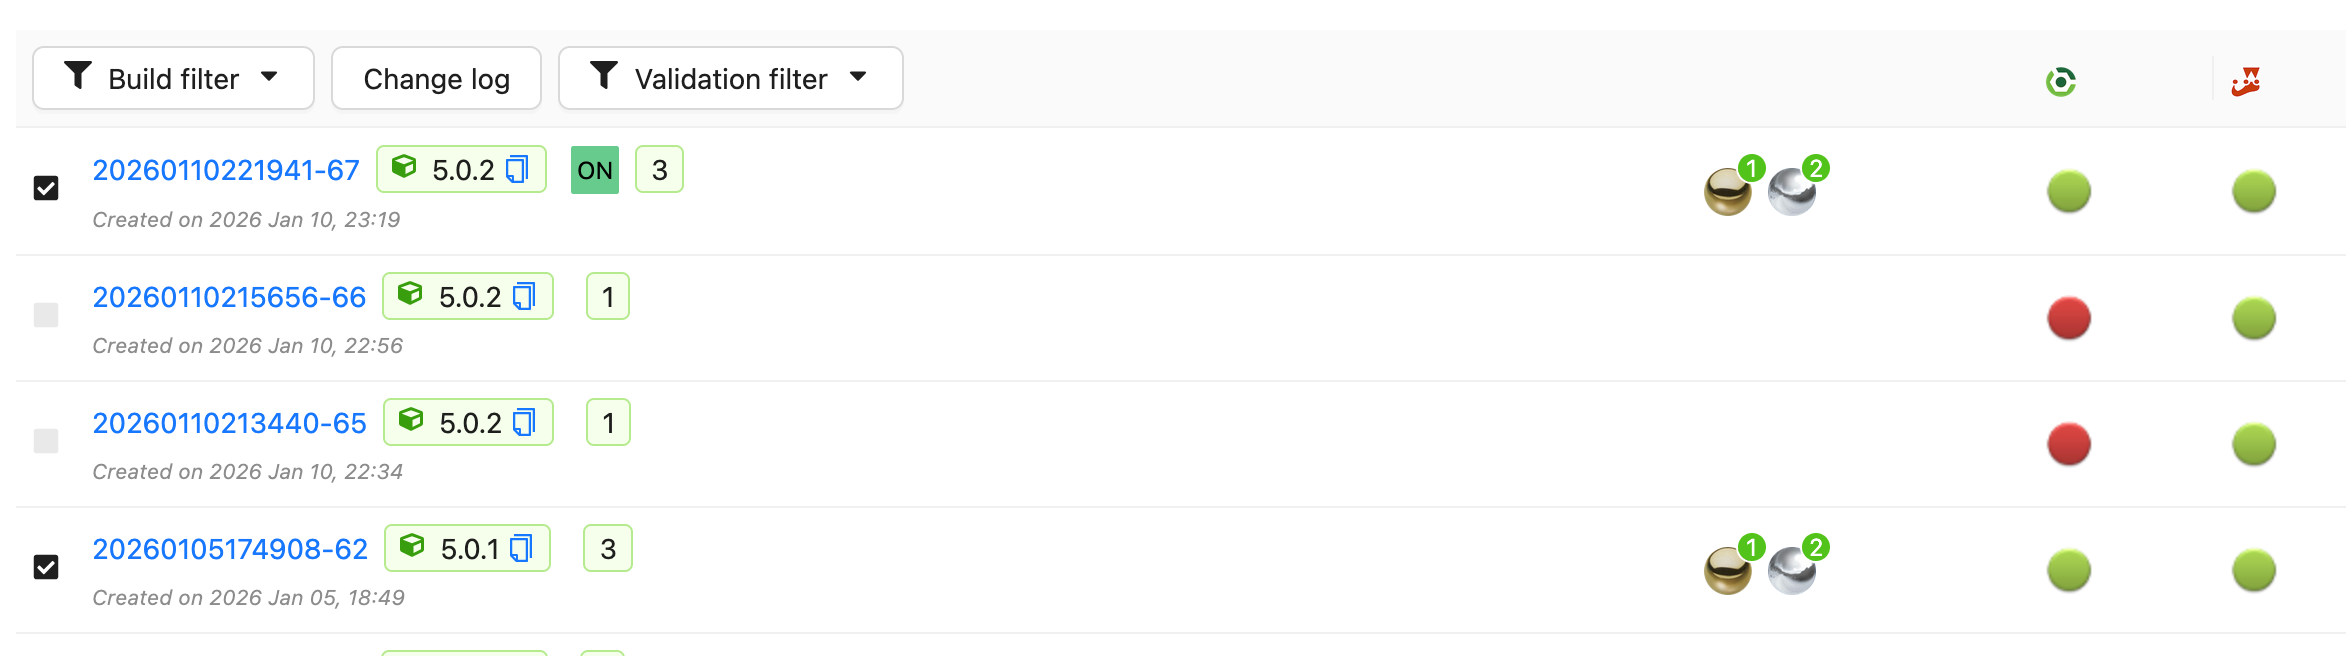
In the UI, a changelog can be generated from the branch page:
- select the boundaries of the changelog
- click on Change log
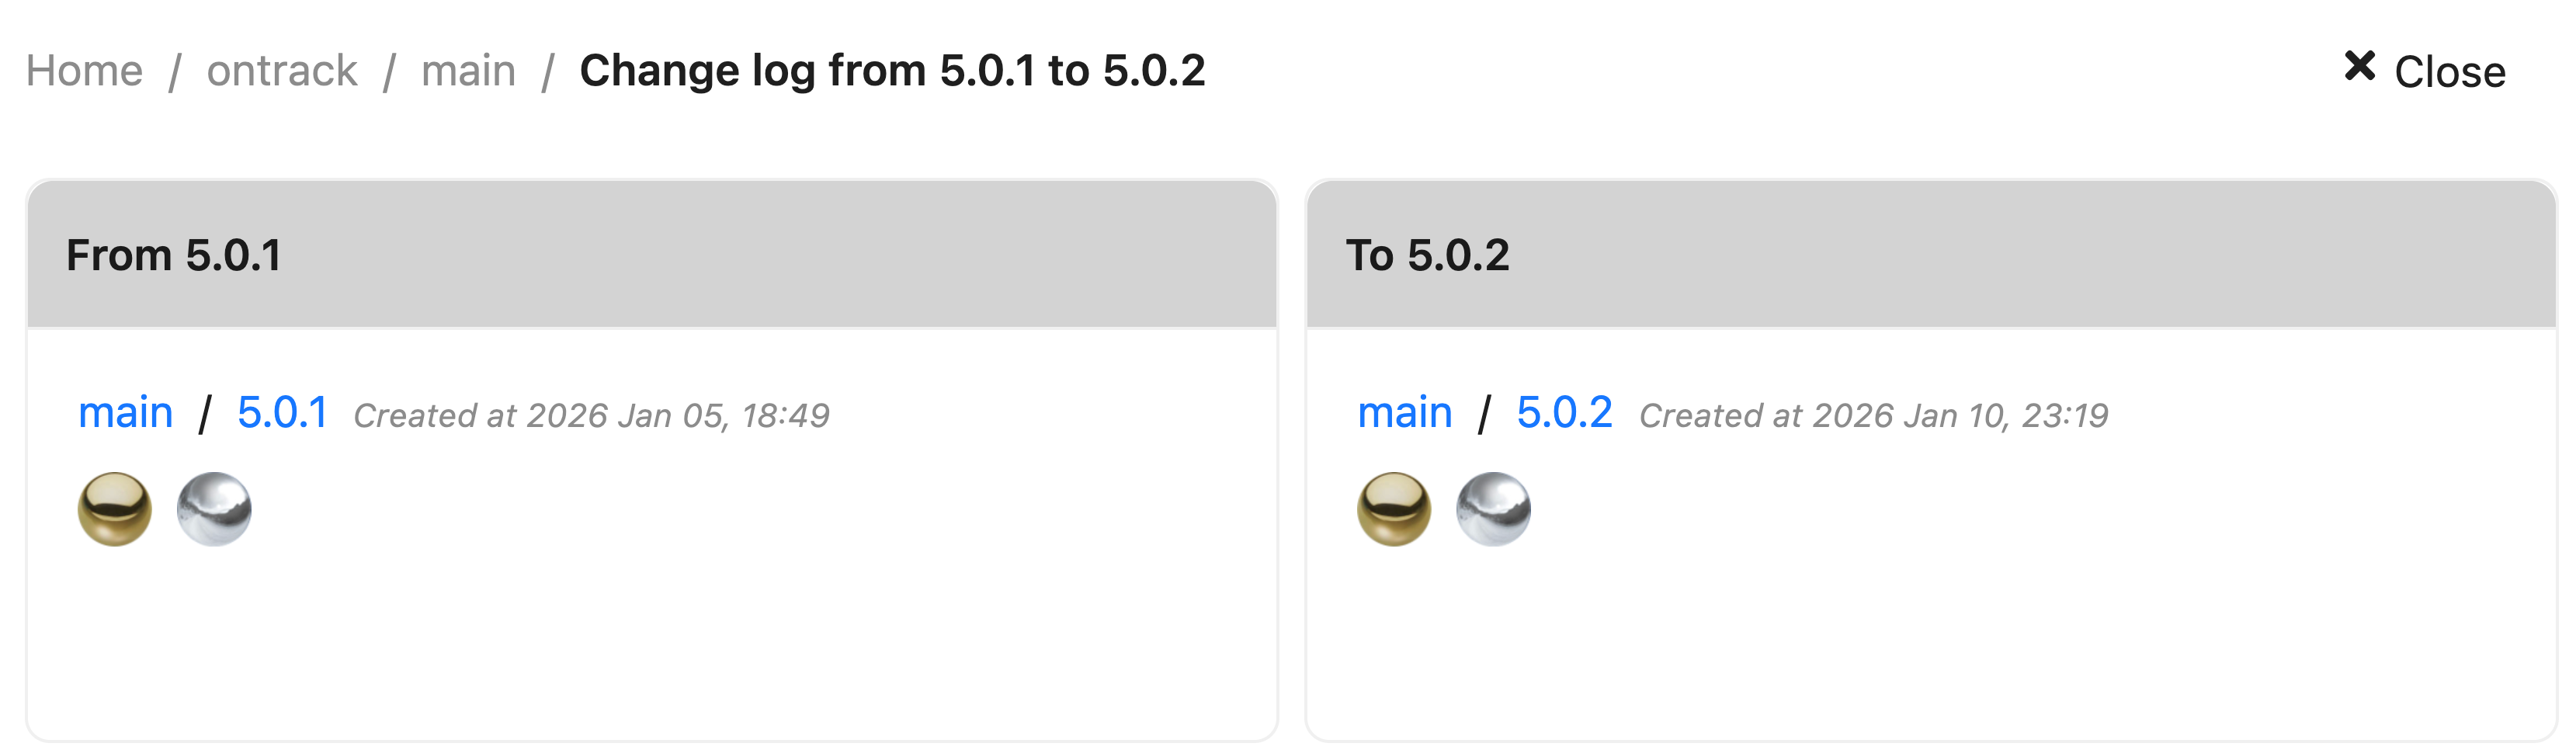
The changelog page displays several sections.
- details about the changelog boundaries:
- list of changes in known dependencies:
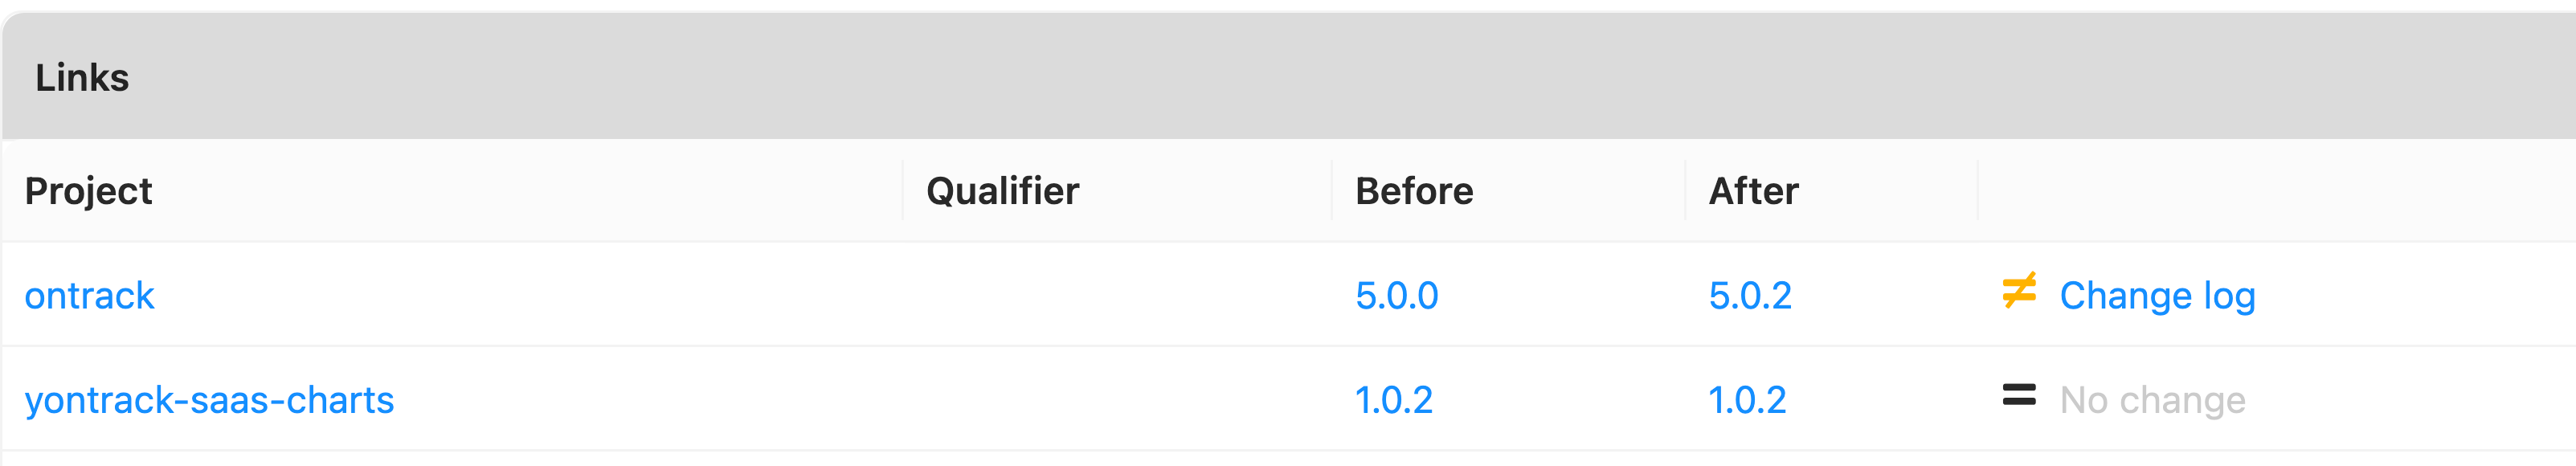
If a dependency has changes, you can drilldown into its own changelog.
- a list of commits for this changelog:
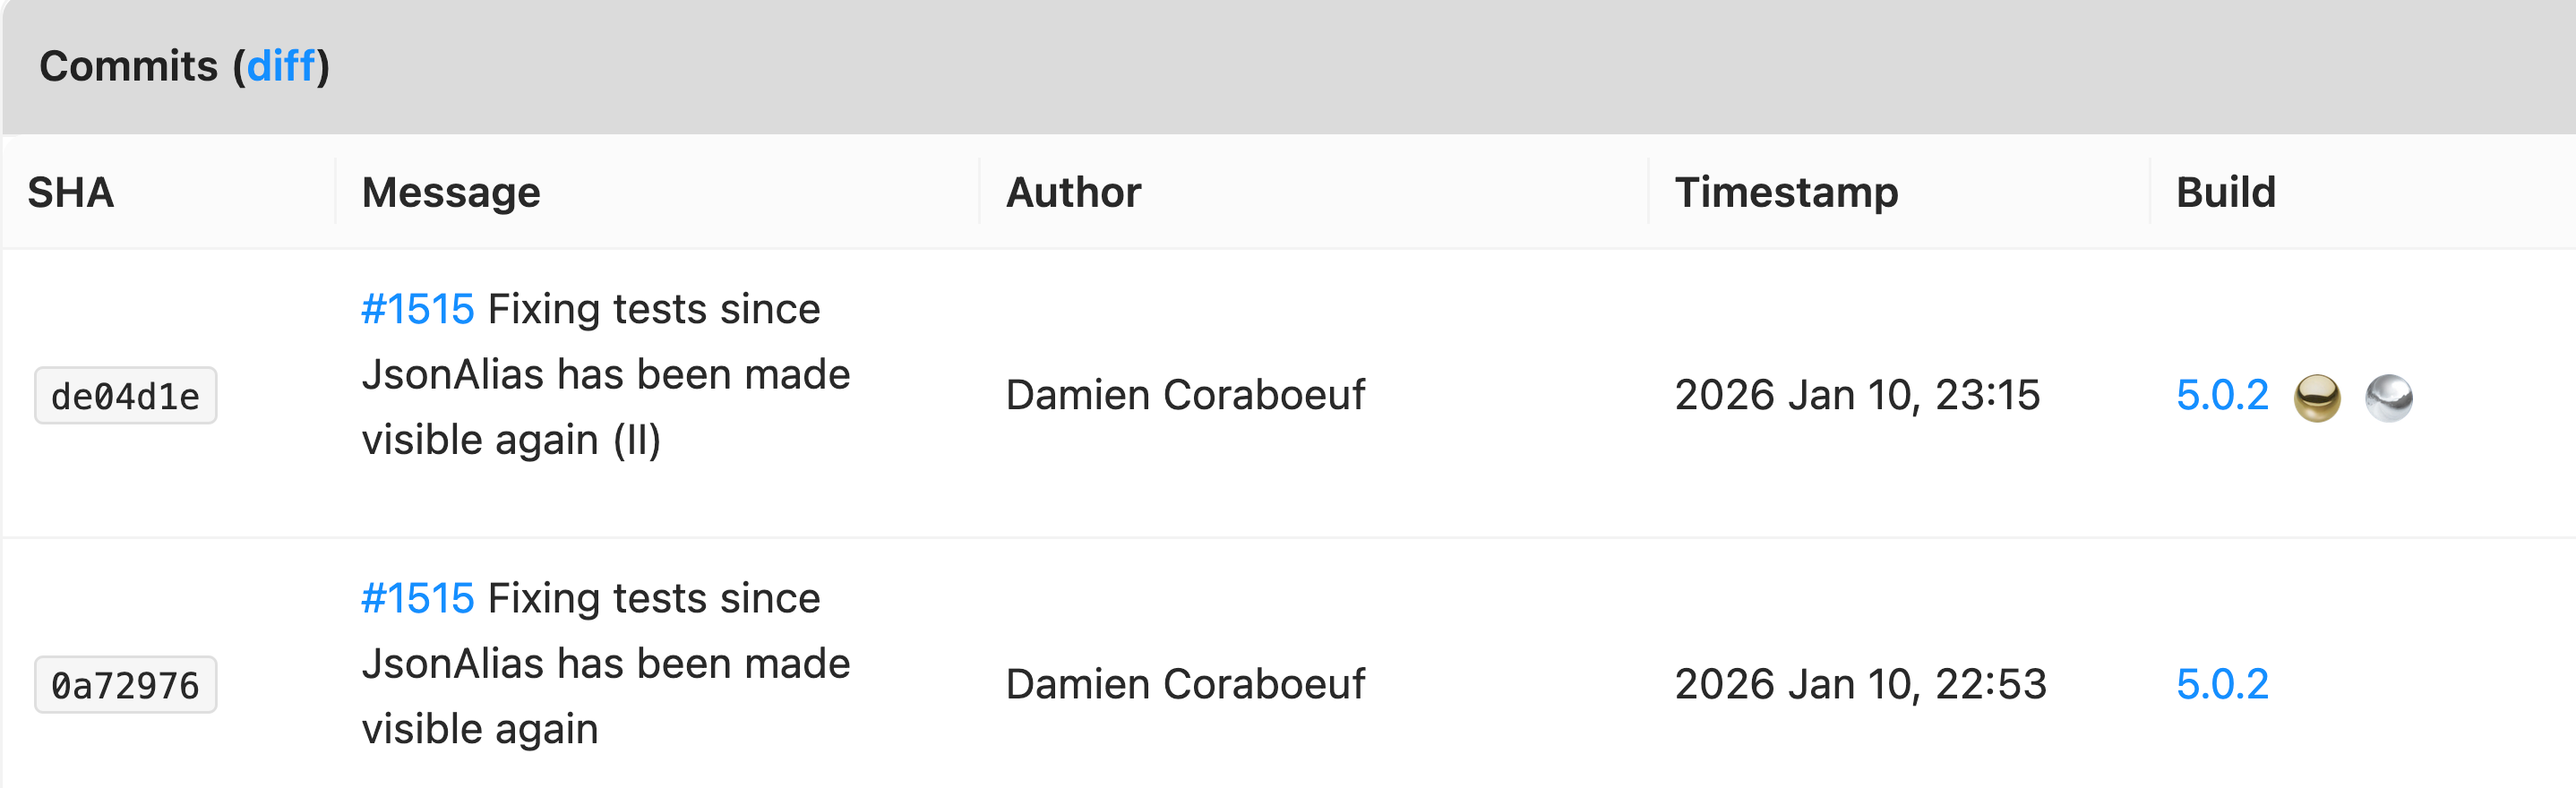
The diff links allows to drilldown into the actual diff of the commits using the associated SCM.
- a list of issues for this changelog:
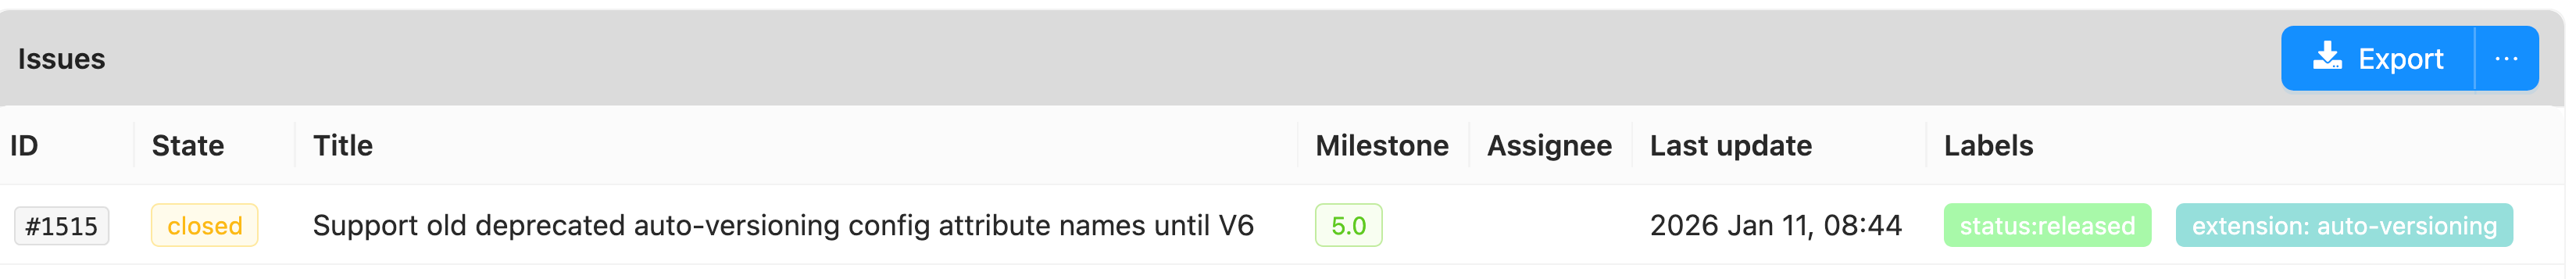
The Export button allows exporting the changelog in different formats:
- HTML
- Jira
- Markdown
- Slack
- Text
Other options are also available to group the issues together.
When you finally click Export, the changelog is shown in a modal box and can be copied.
Note
See also the templating for more advanced usages
Reading the changelog as a semantic changelog
The same changelog can be read in two ways, chosen from the View menu in the page's command bar:
- Classic — the sections described above: boundaries, dependencies, commits and issues. This is what the page shows unless you ask for something else.
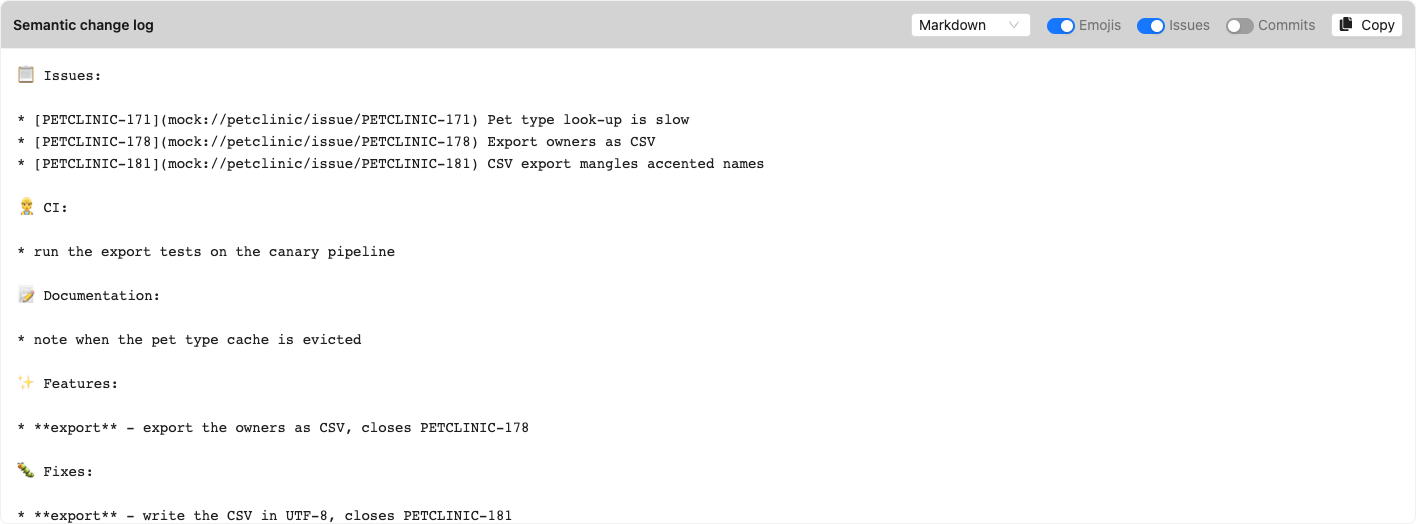
- Semantic — the commits grouped into sections by their conventional-commit type, exactly as the templating renderer produces them for a notification. This is the form you paste into release notes, a pull request description or Jira.
The semantic view replaces the issues section with the rendered changelog, shown as raw text with a Copy button — including for HTML, where the source is what you get, because the point of choosing a format is to paste the result somewhere else. The boundaries and the dependency changes stay: they answer which two builds this is about, whatever way you read it.
The classic view is the one shown in the sections above — the same changelog, read as boundaries, dependencies, commits and issues.
Four options sit in the panel's own header:
| Option | Default | Meaning |
|---|---|---|
| Format | markdown |
The renderer: text, markdown, html, jira or slack |
| Emojis | on | Emojis in the section titles |
| Issues | on | An issues section inside the rendered text — the semantic view has no issues panel |
| Commits | off | Shows the classic commits section beside the rendered text |
The view and its options are remembered in your user preferences, so the changelog page opens the way you last read it, on any machine.
They are also carried in the URL, so a link you share reproduces exactly what you were reading:
/extension/scm/changelog?from=1146&to=1149&view=semantic&format=jira&emojis=true&issues=true&commits=false
The parameters are written only when you change something. A changelog link with no view=
parameter keeps meaning "however you like to read it" for whoever opens it.
Note
The semantic changelog only shows commits whose subject carries a conventional-commit type,
such as feat(api): search owners by phone number. On a project whose commit messages do
not follow that convention, nothing survives that filter: with Issues off the view says so
rather than showing an empty panel, and with Issues on you get the issues section and no
type sections at all. Either way, turn Commits on to read the commits as they are. See
Semantic changelogs for the same rendering used from a template.
Using the UI across branches
You can generate a changelog between two builds on different branches.
Navigate to the project and select Search builds.
Using the filter options, select the builds you want to compare, click on the icon to select the boundaries:
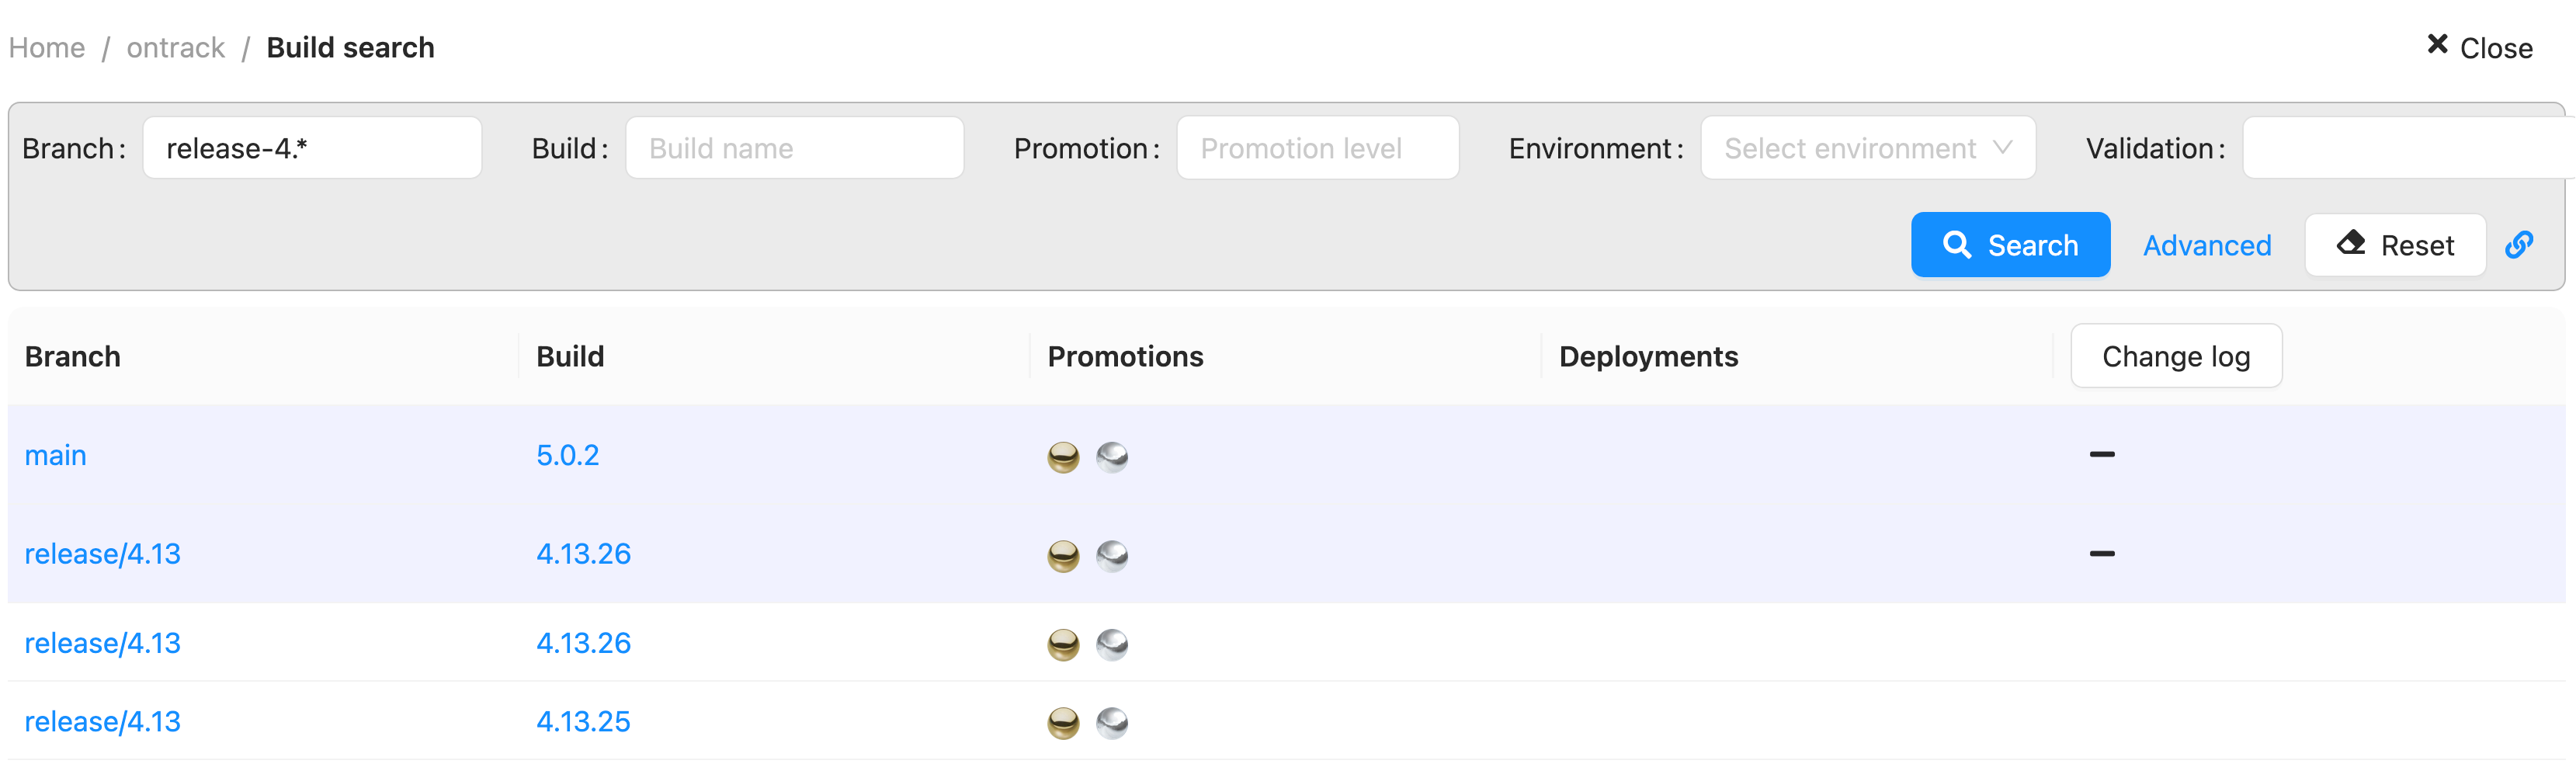
Once you have selected two boundaries, you can click on the Change log button. You'll get the same changelog page as for the branch changelog.
Note
You cannot generate changelogs between different projects.
Using a permalink
The changelog page can be linked to directly, which is useful for release notes, chat messages or CI jobs.
Using the IDs of the two builds:
/extension/scm/changelog?from=1146&to=1149
Using the name of the project and the names of the two builds, which can be written without knowing any ID:
/extension/scm/my-project/changelog?from=1.2.0&to=1.3.0
In this second form, each boundary is looked for using the display name of the builds first, and then using their name.
The boundaries can be given in any order: the changelog is always computed from the oldest build to the most recent one.
If the project, one of the branches or one of the builds cannot be found, the reason is displayed on the page.
Selecting the branch of a boundary
Build names are unique inside a branch, not inside a project. When several builds of the project match a boundary, the most recent one is used.
The branch of each boundary can be given to remove this ambiguity:
/extension/scm/my-project/changelog?from=1.2.0&fromBranch=release-1.2&to=1.3.0&toBranch=release-1.3
Warning
When a branch is given, the name of the build is looked for in this branch only, but its display name is still looked for in the whole project. A boundary given as a display name can therefore be resolved into a build which is not on the branch which has been given.
Giving a branch also changes the order of the matching: without a branch, the display name is matched first, and then the build name. With a branch, the build name is matched first, and then the display name.
Using templating
The most powerful way to generate changelogs is to use templating.
Several template sources are available:
Build.changelog- changelog between this build and anotherPromotionRun.changelog- changelog between a promoted build and the previous promotion-
PromotionRun.semanticChangelog- semantic changelog between a promoted build and the previous promotion
For example, to generate a mail on a promotion containing a semantic changelog, you could use the following template:
${promotionRun.semanticChangelog?issues=true&emojis=true}
In this example, the changelog not only contains the semantic changelog, but also the list of issues if there are any. Each section (features, fixes, etc.) is also decorated with the corresponding emoji.
Using the API
The classic and semantic changelogs can also be generated using the API:
query {
    scmChangeLog(from: 1146, to: 1149) {
        # Classic changelog
        render(config: {commitsOption: ALWAYS}, renderer: "html")
        # Semantic changelog
        semantic(config: {emojis: true}, renderer: "markdown")
    }
}
Note
Using the API directly may be a way to render more complex changelogs on your side.
Using the clients
Using the Yontrack CLI or the Jenkins pipeline library, you can generate changelogs.
Recursive changelogs
Both classic and semantic changelogs can be recursive.
The following options are available:
dependencies: comma-separated list of project links to follow one by one for a get deep change log. Each item in the list is either a project name, or a project name and qualifier separated by a colon (:)allQualifiers: loop over all qualifiers for the last level ofdependencies, including the default one. Qualifiers atdependenciestake precedencedefaultQualifierFallback: if a qualifier has no previous link, uses the default qualifier (empty) qualifier
For example, using templating, you could generate the main changelog between two builds, and then
the corresponding changelog for the library dependency:
${promotionRun.semanticChangelog?issues=true&emojis=true}

${promotionRun.semanticChangelog?issues=true&emojis=true&dependencies=library}
If the library project has a dependency on core, you can even generate a deeper changelog:
${promotionRun.semanticChangelog?issues=true&emojis=true}

${promotionRun.semanticChangelog?issues=true&emojis=true&dependencies=library}

${promotionRun.semanticChangelog?issues=true&emojis=true&dependencies=library,core}
Commit messages
Wherever a changelog renders a commit, it renders only the first line of its message - the subject - and truncates it at 100 characters, ellipsis included. Commit messages, in particular the ones written by coding agents, routinely run to dozens of lines, and a changelog is a list of subjects.
This applies to the changelog page, to the changelogs rendered through templating and the API, and to the description of a commit in the search results.
The full message is never lost: it is stored as-is, indexed in full by the search - so that looking for a phrase in the body of a commit still finds it - and displayed in full on the commit page, one click away from the changelog.
The maximum length can be changed for the changelogs rendered through templating or the API, using
the commitsMaxLength option, common to classic and semantic changelogs:
${promotionRun.changelog?commitsOption=ALWAYS&commitsMaxLength=250}
Setting commitsMaxLength to 0 disables the truncation - the subject is then rendered in full,
however long it is. It does not bring the body of the message back: only the first line is ever
rendered in a changelog.
The length used on the changelog page and in the search results is not configurable.
Issues of a commit
The issues of a changelog are the ones its commits name. A commit names its issues in two places only:
- its subject - the first line of its message;
- its trailer lines - any line of the body which starts, in any case, with one of the keywords below, with or without a colon. The rest of that line is the value of the trailer.
| Keywords |
|---|
close, closes, closed |
fix, fixes, fixed |
resolve, resolves, resolved |
ref, refs, references, related |
issue, issues |
jira-ticket |
Every issue key found in the subject or in a trailer value is linked, so a trailer can name several issues:
#12 Search owners by phone number

The search used to ignore the phone numbers, see the discussion in #10.

Closes #12, #13
Refs: ABC-1 ABC-2
Jira-Ticket: ABC-3
This commit names #12, #13, ABC-1, ABC-2 and ABC-3. The rest of the body is prose, and is
ignored: #10 above is mentioned, not worked on, and is not part of the changelog.
The rule is fixed and has no setting. It applies to the issues of a changelog, wherever it is rendered - the changelog page, the issue export, templating, the API and notifications - and to the issues the search finds in the commits of a project.
For GitHub and GitLab issues, a #123 is not an issue of the repository when it is part of a
reference to another repository (owner/repo#123), of a URL, or of an HTML entity ('), or when
it is directly followed by a letter or an underscore (#123abc).
Agent markers
Each commit of a changelog knows the assistants - the kinds of coding agents, like Claude Code, Codex, Copilot or Devin - which helped write it. Yontrack reads them from the markers git carries: the trailers of the commit message, its author and its committer.
Nothing is stored: the assistants are read from git every time the changelog is computed, so git stays the truth, and changing the settings below changes what the existing changelogs show.
The assistants of a commit are available in the API, as the assistants field of
a commit:
{
  scmChangeLog(from: 100, to: 110) {
    commits {
      commit {
        id
        assistants {
          name         # Claude Code, Codex, Copilot, Devin...
          markers      # CO_AUTHOR, ASSISTED_BY, SESSION_TRAILER, TRAILER, AUTHOR, COMMITTER
          sessionLink  # e.g. the Claude-Session URL, when a trailer carries one
        }
      }
    }
  }
}
An assistant appears once per commit, with all the markers which named it, and the first session link found.
On the changelog page
On the changelog page, a commit written with an assistant shows a small
assisted marker next to its message. Its tooltip lists the assistants, and when the commit
carries a session link (a Claude-Session: trailer), the marker opens the agent session in a new
tab.
The header of the changelog says how many of its commits are assisted, e.g. 1 of 12 commits assisted. It says nothing when no commit is assisted.
In templates
The changelogs rendered through templating - Build.changelog,
PromotionRun.changelog and the changelog field of a deployment - take two options, both off by
default, so that the existing templates render as before:
assistants=true- each commit line is followed by its assistants, e.g.(assisted by Claude Code). In Markdown and HTML, the name of an assistant links to its agent session when the commit carries one. It applies to the commits, so only when they are rendered (seecommitsOption);assistedCount=true- the changelog starts with the number of its assisted commits, e.g.3 of 12 commits assisted.
For example, for the body of a pull request:
${promotionRun.changelog?commitsOption=ALWAYS&assistants=true&assistedCount=true}
renders, in Markdown:
1 of 2 commits assisted

* [ISS-12](https://example.atlassian.net/browse/ISS-12) Search owners by phone number

Commits:

* [a1b2c3d](https://github.com/org/repo/commit/a1b2c3d) ISS-12 Fix the export (assisted by [Claude Code](https://claude.ai/code/session_0123))
* [e4f5a6b](https://github.com/org/repo/commit/e4f5a6b) ISS-12 Search owners by phone number
The assistants of the commit of a build are also available on their own, as a comma-separated list of names, empty when there is none:
${build.scmCommit?field=assistants}
What is recognised
Only the trailer block of a message is read: its last paragraph, the subject excepted. A line looking like a trailer anywhere else in the body is prose. Trailer keys ignore the case.
These conventions are built in:
| Marker | Assistant |
|---|---|
Co-Authored-By: … <noreply@anthropic.com> |
Claude Code |
Co-authored-by: … <codex@openai.com> |
Codex |
Co-authored-by: … <copilot@github.com>, or copilot@github.com as author email |
Copilot |
Assisted-by: <name> |
the name, up to its first : |
Claude-Session: <url> |
Claude Code, the URL being the session link |
copilot-swe-agent[bot] as author or committer login |
Copilot |
devin-ai-integration[bot] as author or committer login |
Devin |
Assisted-by: is the convention of the Linux kernel and of Fedora, where its value reads
AGENT_NAME:MODEL_VERSION: Assisted-by: Claude:claude-opus-4 names the assistant Claude.
A login is the account of the author or committer in the SCM, when the SCM gives one (GitHub does), or the name git records for them: bots commit under their login.
For example, this commit has two assistants, Claude Code (CO_AUTHOR and SESSION_TRAILER, with
its session link) and Codex (ASSISTED_BY):
#12 Search owners by phone number

Co-Authored-By: Claude Opus 4 <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_0123
Co-Authored-By: Jane Doe <jane@example.com>
Assisted-by: Codex:gpt-5
Human co-authors are not assistants
A Co-Authored-By trailer counts only when its email is an agent's. Pairing and squashed
contributions make human co-authors common, and counting them would flag as assisted every commit
two people wrote together: Jane Doe above is a co-author, not an assistant.
An email which only looks like an agent's - noreply@anthropic.com.example.com,
fake-noreply@anthropic.com - is not one either: the emails are matched as a whole.
Settings
The Agent markers settings, in the user menu at System > Settings, tune the recognition:
- Built-in conventions - on by default, switches the whole table above on or off;
- Patterns - additional rules, which add to the built-in conventions. They are how an enterprise
recognises its internal agents. Each pattern has:
- a name - the assistant to report;
- a type - what the value is matched against:
CO_AUTHOR_EMAIL- a regular expression matching the whole email of aCo-Authored-Bytrailer;TRAILER- a trailer key, whatever the value of the trailer;AUTHOR_EMAIL- a regular expression matching the whole email of the author;LOGIN- the exact login, or name, of the author or of the committer;
- a value - the regular expression, the trailer key or the login. Regular expressions, trailer keys and logins ignore the case.
An invalid regular expression is rejected when the settings are saved.
Only the administrators save the settings, but whoever can create builds on at least one project
reads them - CI accounts and agent tokens included - through the
settingsById query:
{
  settings {
    settingsById(id: "agent-markers") {
      values  # { builtInConventions, patterns: [{ name, type, value }] }
    }
  }
}
The markers decide no permission and hold nothing secret. When Yontrack has no SCM for a project,
yontrack build assisted --from-git A..B parses the trailers of the range on the CI, and reads these
settings to apply the custom patterns as the server would. A token which cannot read them gets the
built-in conventions only, with a warning.
The settings can be set as code, under
ontrack.config.settings.agent-markers:
ontrack:
  config:
    settings:
      agent-markers:
        builtInConventions: true
        patterns:
          - name: Acme Bot
            type: CO_AUTHOR_EMAIL
            value: .*-bot@acme\.com
          - name: Acme Agent
            type: TRAILER
            value: Acme-Agent-Run
          - name: Acme Bot
            type: LOGIN
            value: acme-bot[bot]
Configuration of changelogs
Besides the recursivity options, the two types of changelogs have their own configuration.
Classic changelogs
These changelogs display the list of issues between two builds. Optionally, the commits can be displayed as well using
the commitsOption parameter.
| Option | Type | Default value | Description |
|---|---|---|---|
| empty | String | Empty | String to use to render an empty or non existent change log |
| title | Boolean | false | Include a title for the changelog |
| commitsOption | (1) | NONE | Option to display commits |
| commitsMaxLength | Int | 100 | Maximum length of a commit message, 0 to disable the truncation |
(1) the possible values for commitsOption are:
- NONE - Never rendering the commits (the default)
- OPTIONAL - Only rendering the commits if no issue is present
- ALWAYS - Always rendering the commits (additionally to the issues)
Semantic changelogs
The semantic changelog is based on the conventional Commits
specification. The changelog page can be read this way too — see
Reading the changelog as a semantic changelog;
the options below are the ones available from a template, of which the page exposes issues and
emojis.
| Option | Type | Default value | Description |
|---|---|---|---|
| issues | Boolean | false | Must a section for changelog actual issues be present? |
| sections | List (1) | Empty | Mapping types to section titles |
| exclude | List (2) | Empty | Types to exclude from the changelog |
| emojis | Boolean | false | Use emojis in the section titles |
| commitsMaxLength | Int | 100 | Maximum length of a commit message, 0 to disable the truncation |
(1) use the sections option to redefine the title of a given semantic type. For example, if you want to use Other
for chore and Bugs for fix, you can use the following configuration:
${promotionRun.semanticChangelog?sections=chore=Other§ions=fix:Bugs}
(2) use the exclude option to exclude some semantic types from the changelog. For example, to skip the generation for
the CI & Build types:
${promotionRun.semanticChangelog?exclude=ci&exclude=build}